Call Quality
Every conversation processed by Aelo receives an automated quality analysis. The AI evaluates the conversation across multiple dimensions and produces a comprehensive report including scores, metrics, sentiment, and actionable coaching suggestions.
Owner Admin Supervisor Rep (own records)
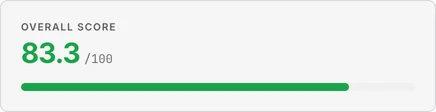
Each record receives a Quality Score from 0 to 100:
| Range | Band | Color |
|---|---|---|
| 80–100 | Excellent | Green |
| 60–79 | Good | Teal |
| 40–59 | Fair | Amber |
| 0–39 | Poor | Red |
The call card shows the score as a number out of 100 with a bar in the band’s color; the band name itself is not printed on the card.
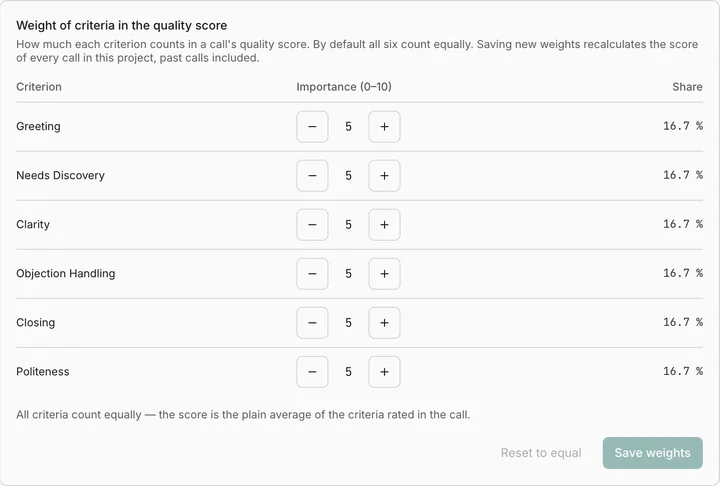
The quality score is the average of the individual sub-metric scores that apply to the conversation. By default every sub-metric counts equally — a plain arithmetic mean. A project can give each of the six quality criteria its own weight from 0 to 10 in project settings → Analysis & Quality (anyone who can edit the project and whose access includes call quality figures); the score is then a weighted average, and a criterion with weight 0 is not counted. A sub-metric that doesn’t apply to a given conversation is skipped rather than counted as zero, and its weight goes to the sub-metrics that were rated; if every rated sub-metric weighs 0, the call has no score.
New weights rescore past calls wherever the score is read — the call card, the call list, dashboards, rep ratings and the public API. What already happened with the old weights is not rewritten: the score already written to the CRM field, alerts that fired, routing decisions and digests already delivered keep the score they were made with. The call card says so when a call’s CRM and alert score was computed with different weights. Before saving, the confirmation shows how the new weights would change the project’s calls of the last 30 days. Which sub-metrics are scored depends on the evaluation profile applied to the record — which modules it turns on (for example, politeness belongs to the profile’s “Emotions & Sentiment” module) — and on the conversation itself: its category and channel. The profile is chosen for each record in a fixed order, described in Evaluation Profiles.
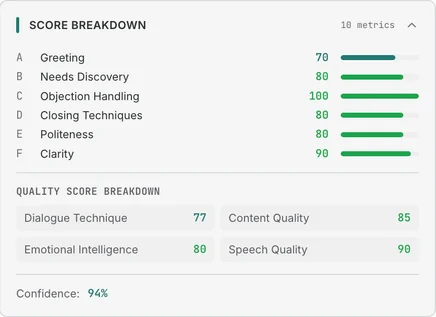
The Score Breakdown card sits in the Score group of the call panel (the pills at the top of the panel — All, Score, Script rules, Criteria, Speech, Insights — switch between groups). It has two parts:
- Six rows, A–F — each with its own 0–100 rating and a bar: A Greeting, B Needs Discovery, C Objection Handling, D Closing Techniques, E Politeness, F Clarity. These six are the sub-metrics the overall quality score is averaged from. A row the profile or the conversation did not score shows “—”.
- Quality Score Breakdown — a grid of the model’s own group scores: Dialogue Technique, Content Quality, Emotional Intelligence and Speech Quality. They are shown for reference and are not part of the average; not every analysis carries them, so the grid may be absent.
The card header counts the metrics shown (for example, “10 metrics”), and its footer shows Confidence — the model’s own confidence in the analysis, when the analysis carries it.
The score has no compliance component: the recording disclaimer, mandatory phrases, profanity and forbidden words are not checked by the analysis profile and do not enter the score — built-in criteria check them, and their answers are shown in the Criteria group of the call panel. Calls analyzed before this change keep the compliance sub-score they already have, and it appears as a Compliance cell in the grid.
When the project sets its own weights, each of the six rows also shows its share in this call’s score (for example, “weight 25 %”).
CRM completeness is analyzed and shown on the record as its own compliance indicator — it no longer contributes to the quality score.
For sales-oriented conversations, Aelo estimates a Sale Probability (0–100%). The AI derives this estimate from the conversation alone:
- Rep’s qualifying behavior (BANT methodology)
- Objection handling effectiveness
- Customer engagement signals
- Closing technique quality
The Sale Probability card (also in the Score group) shows the percentage with a bar, the Confidence level (High, Medium or Low) when the analysis carries it, the note that this is an AI estimate, and — when present — a Key Factors list: each factor is marked ▲ (raises), ▼ (lowers) or ● (neutral).
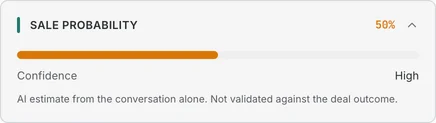
This is an AI estimate, not a forecast. It is not validated against the actual outcome of the deal, so it is shown on the individual conversation — beside the transcript it was derived from — and is deliberately not aggregated into a dashboard KPI.
Aelo evaluates the sentiment expressed by the customer during the conversation. Aelo does not score the emotion of reps or other employees, in line with the EU AI Act (Art. 5(1)(f)).
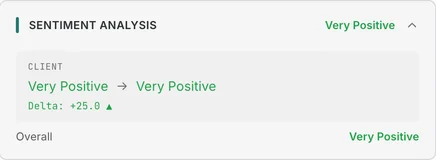
The Sentiment Analysis card (in the Speech group, next to the Politeness and Clarity cards) shows:
| Indicator | Description |
|---|---|
| Client | The customer’s sentiment at the start of the conversation → at the end |
| Delta | The change between start and end, in green with ▲ when it is up or flat and in red with ▼ when it went down |
| Overall | The sentiment of the conversation as a whole; also shown in the card header |
Sentiment is shown on a five-step scale: Very Positive, Positive, Neutral, Negative, Very Negative. The card has no timeline: it shows where the customer started, where they ended and the difference, not a curve over the conversation.
The analysis extracts:
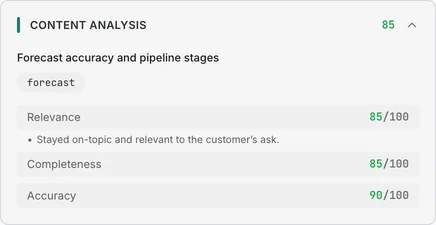
- Keywords — frequently mentioned terms and phrases
- Topics — main subjects discussed during the conversation
- Key Moments — critical points in the conversation (e.g., objection raised, price discussed, commitment made)
Key moments are shown in the Errors & Key Moments card (in the Insights group) together with the rep errors the analysis found. An error is tagged Error — text with no quote and no time. A key moment is tagged Key: it says what happened and, when the analysis gives them, who spoke ([Rep], [Client] or [Role unknown]) and the words verbatim. Its time is a button: while the record’s Transcript tab is open, a click plays 20 seconds of the recording from that point; a time beyond the end of the recording is not shown.
Each analysis includes a natural language Summary — a concise paragraph describing what happened in the conversation, key outcomes, and notable events.
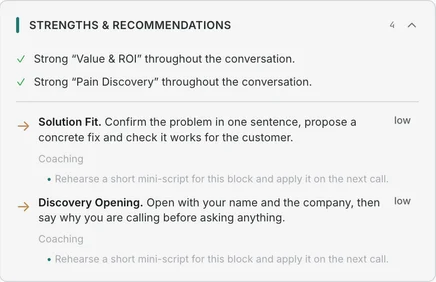
The Strengths & Recommendations card (in the Insights group; the number in its header is strengths plus recommendations) lists, without sub-headings:
- strengths, each marked ✓ — what the rep did well (e.g., “Strong “Value & ROI” throughout the conversation.”)
- below a divider, the recommendations block, each marked → — specific, actionable advice (e.g., “Discovery Opening. Open with your name and the company, then say why you are calling before asking anything.”)
A recommendation is its text and a priority tag:
- the text: a bold lead naming the criterion, followed by the advice (with no criterion name, the advice stands alone);
- the priority tag: in analyses of your conversations it currently always reads “Medium”; “High” and “Low” appear only in demo records.
In demo records the advice also carries a category and a short action step.
The score of a single conversation shows how well it followed the script. To see which steps the team drops again and again, open the Missed script steps card on the dashboard’s Quality tab and its Report “Script Steps” → link. The report breaks every step down by rep and by criterion — see Steps Report.
Quality columns (score, sale probability, sentiment, and A–F component scores) are available directly in the Conversations list. Individual columns can be toggled via the table’s column switcher. The list can be filtered by:
| Filter | Options |
|---|---|
| Score Range | Minimum and/or maximum quality score — the same score the dashboard averages, with one decimal; a range such as 0–79 includes everything below 80 (79.5 too), so adjacent ranges never overlap or leave a gap |
| Sentiment | Positive, Neutral, Negative |
| Date Range | Start and end date |
| Project | Filter by project |
| Rep | Filter by specific rep |
Owner Admin Supervisor Rep
Analyses are exported from the Conversations page, not from here: the list exports as CSV, JSON or to the clipboard with the current filters applied, a selection adds Export to MD, and Export in an open record downloads its PDF report. A Rep exports only their own records.
| Feature | Owner | Admin | Supervisor | Rep |
|---|---|---|---|---|
| View all analyses | ✅ | ✅ | ✅ (project-scoped) | ❌ |
| View own analysis | ✅ | ✅ | ✅ | ✅ |
| Score breakdowns | ✅ | ✅ | ✅ | ✅ (own) |
| Filter analyses | ✅ | ✅ | ✅ | ❌ |
| Export reports | ✅ | ✅ | ✅ | ✅ (own) |
Note: Reps see their own quality data on the Mine tab of the Dashboard and their own records in the conversations list.
- Focus on the recommendations — these are the highest-impact coaching opportunities.
- Track score trends over time to measure coaching effectiveness.
- Use sentiment filters to quickly find conversations where customers were dissatisfied.
- Compare rep scores within the same project for fair benchmarking (different projects may use different evaluation profiles).
- Re-analyze records after updating evaluation profiles to see the impact of the change on the score.